Thomas Ahle

Blog

Adversarial Examples for Fast Hash Functions

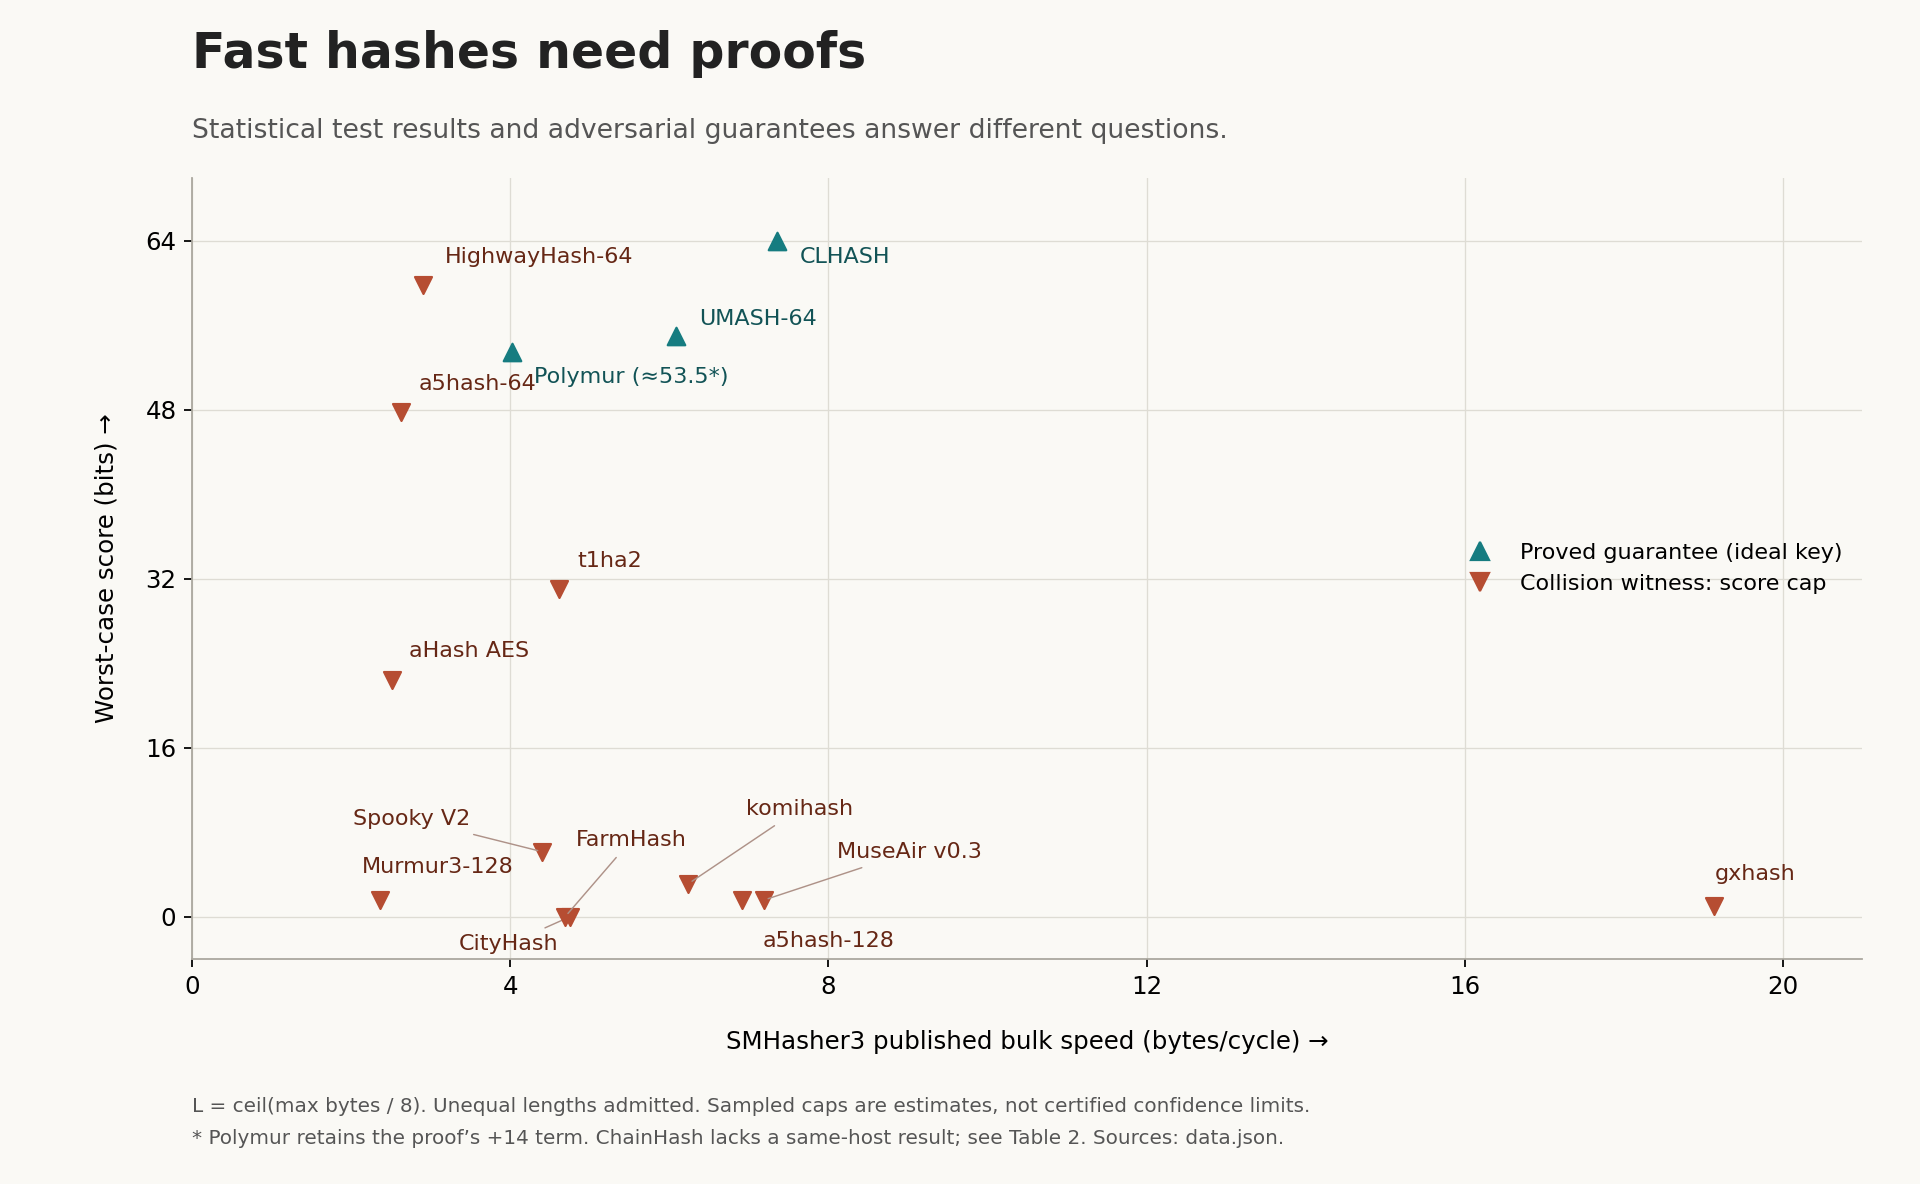
Explicit colliding inputs for komihash, a5hash, MuseAir, t1ha2, HighwayHash and others under random seeds, measured as worst-case collision bits, next to hash functions with proven bounds and their speed.

Read more
Simple Stirling Upper/Lower Bounds

A short, elementary route from n! = ∫ x^n e^{-x} to sharp Stirling bounds via a Gaussian change of variables—and a natural path to the full expansion.

Read more

Analysis of Ornstein-Uhlenbeck Process for Linear Systems

This blog post delves into the Ornstein-Uhlenbeck (OU) process and its application in the analysis of linear systems. We explore how the OU process, when applied to a Positive Semi-Definite (PSD) matrix and a specific vector, leads to more efficient and accurate sampling strategies.

Read more

A Differentiable Top-k Layer for PyTorch

Binary-search a scalar shift, reuse it in backprop via implicit differentiation, and you get a simple, exact top-k relaxation that plays nicely with PyTorch autograd.

Read more

ZipLM with Beam Search, BPE and Progressive Compression

ZipLM uses Gzip to create a language model, however it is quite bad. This post shows how to use beam search to improve the output of ZipLM. When sampling sentences from "The Great Gatsby," the raw model produces near-gibberish. However, implementing beam search yields increasingly coherent sentences as the beam width increases, although performance is still poor compared to older models.

Read more

Liar’s Dice by Self-Play

I’ve been meaning to learn about AIs for games like Poker or Liar’s Dice for a while. Recently while reading DeepMind’s article Player of Games, I thought I might be able to make something really simple that works well enough to be fun. “It shouldn’t take more than an afternoon,” I thought. Of course, I ended up spending much more time on it, but it did turn out to be fun and very simple.

Read more

An Evolutionary Data Structure for Sets

I recently published a preprint, together with Jakob Knudsen, describing a new, optimal data structure for set similarity search. An interesting way to look at this is as an Evolutionary Algorithm (aka genetic algorithm). We think it's probably the first time the provably best way to solve a problem has been evolutionary. This post won't go deep into the mathematics, but will contain code samples and some fun gadgets I built to simulate it.

Read more

Another Tail of the Hypergeometric Distribution

This blog post sheds light on the less-discussed sampling without replacement scenario, its implications in algorithm analysis, and how it compares with its more famous counterpart, the binomial distribution.

Read more